KServe: a control plane builds the model servers, a data plane answers

Scroll or pinch to zoom, drag to move, double-click to zoom in 100% SVG PNG Back to the post
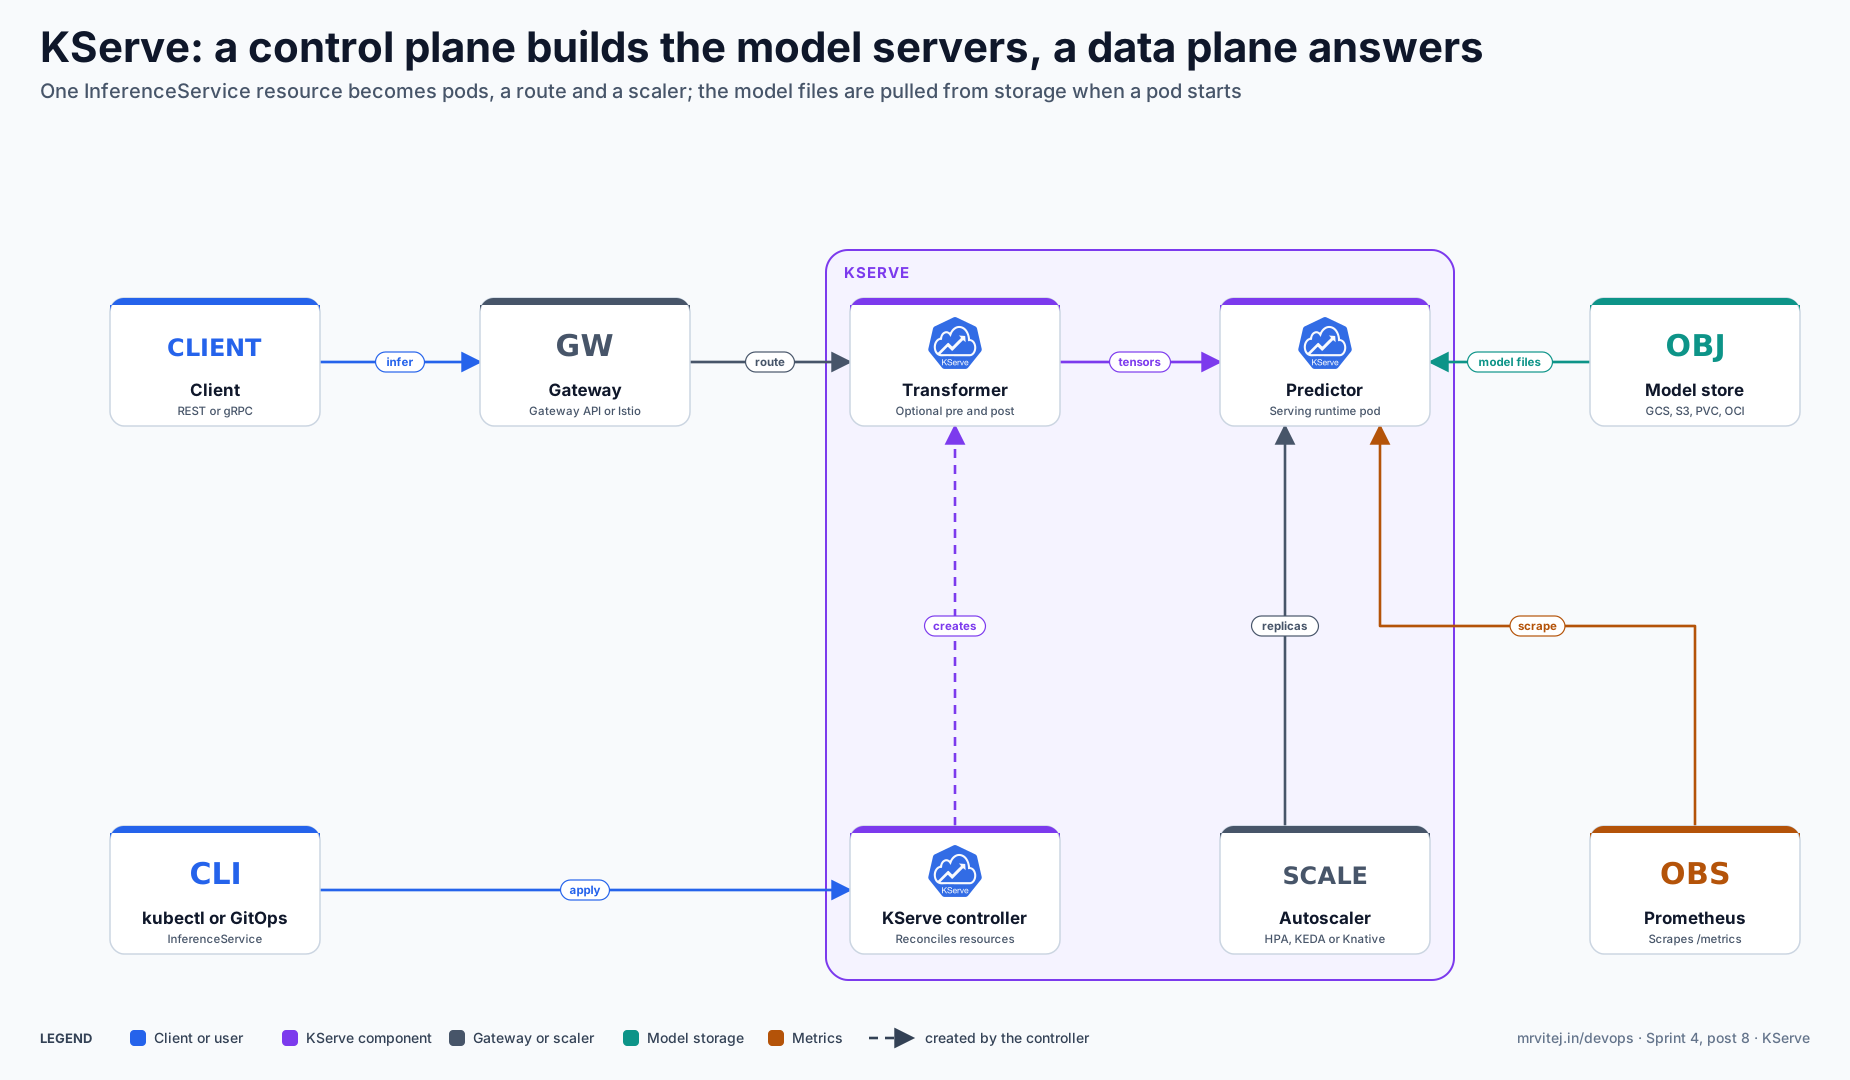
KServe architecture: a client sends REST or gRPC inference requests to a gateway, which routes to an optional transformer and then to the predictor pod running a serving runtime; the predictor pulls model files from a model store such as Google Cloud Storage; users apply an InferenceService with kubectl or GitOps, and the KServe controller creates the transformer and predictor resources; an autoscaler sets the number of predictor replicas; Prometheus scrapes metrics from the pods.